This event is over.
Thank you for joining us at OCP Global Summit 2026.
Oct 12 - 15 , 2026
Oct 12 - 15 , 2026
Oct 12 - 15 , 2026
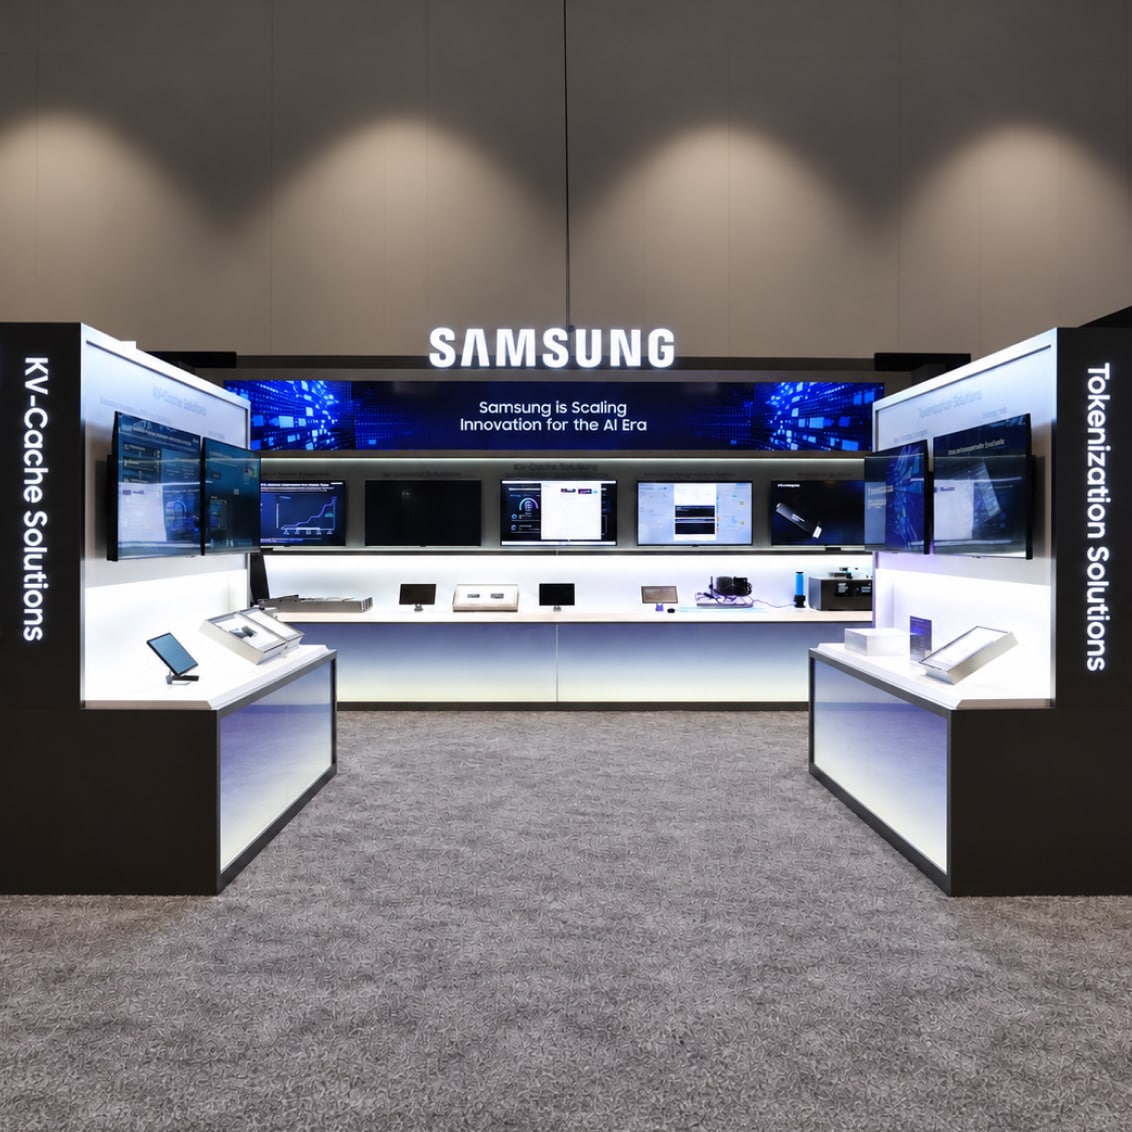
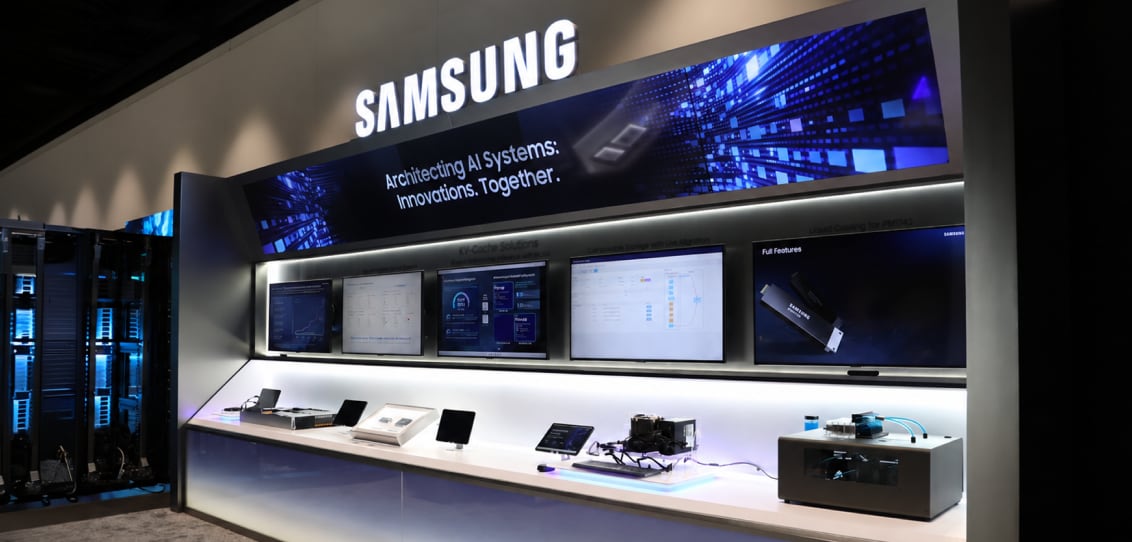
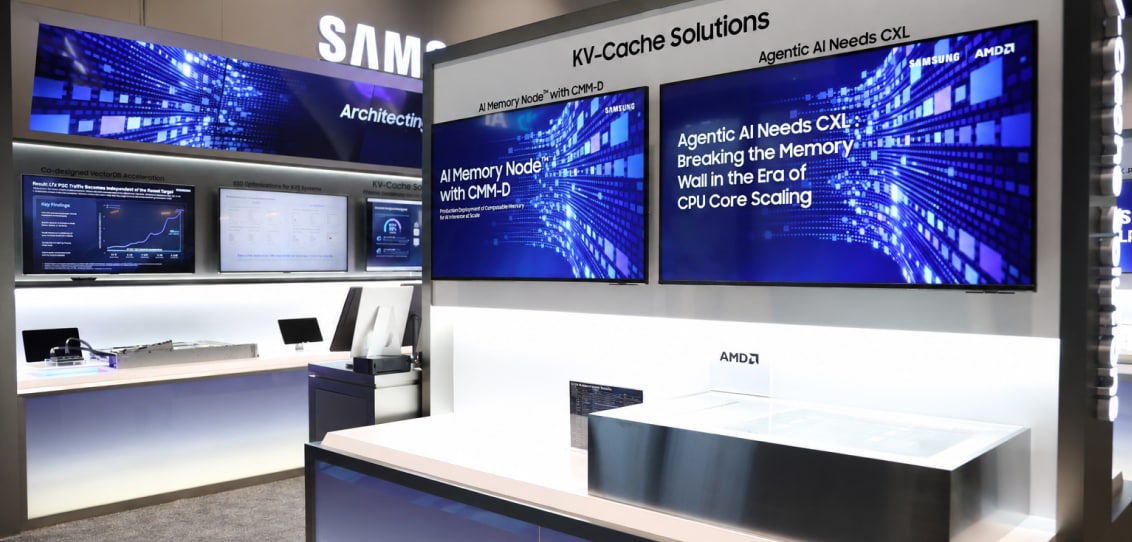
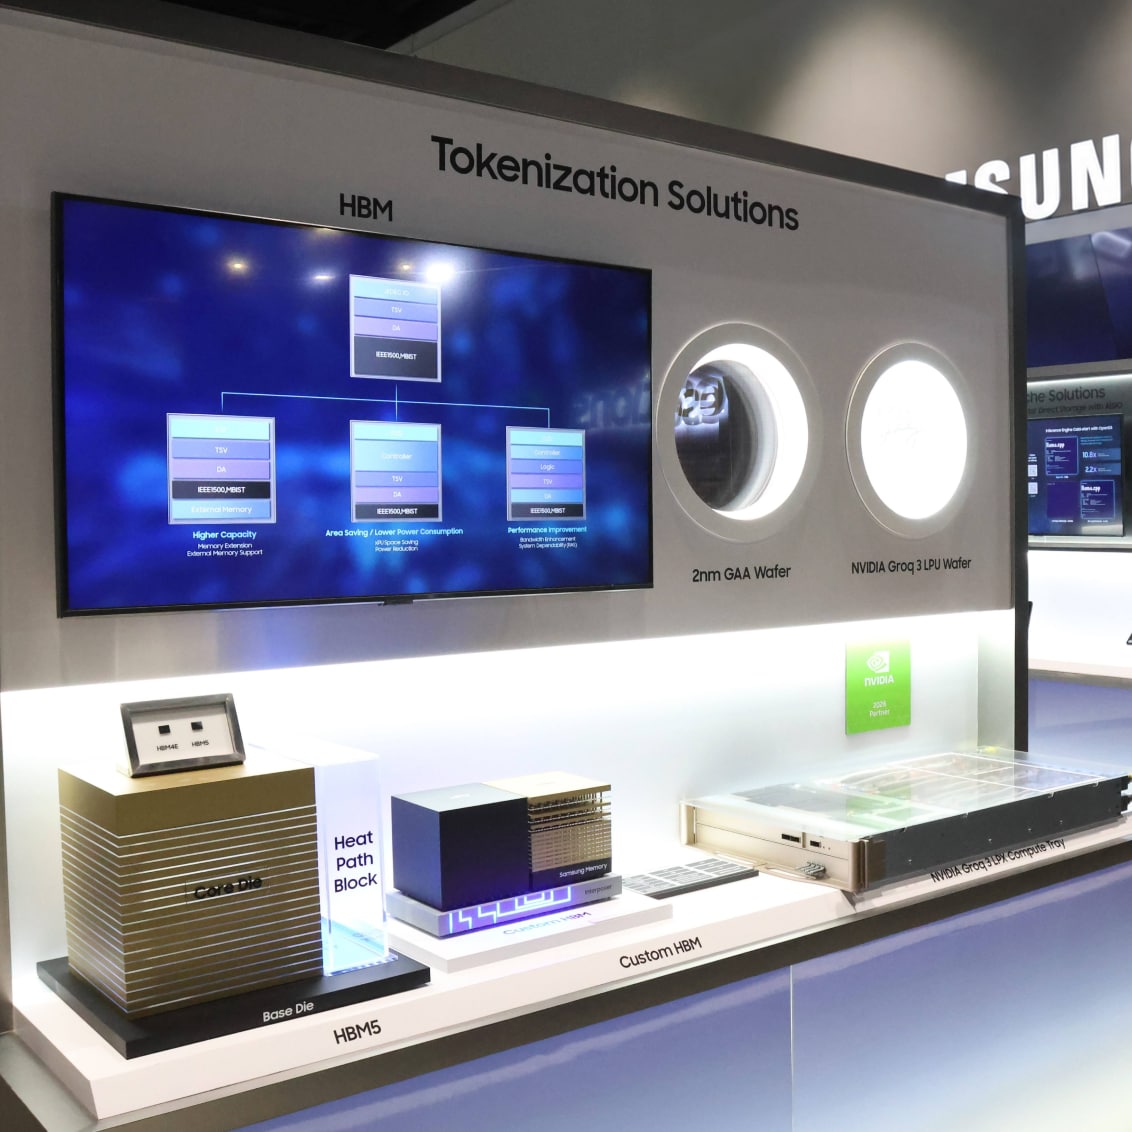
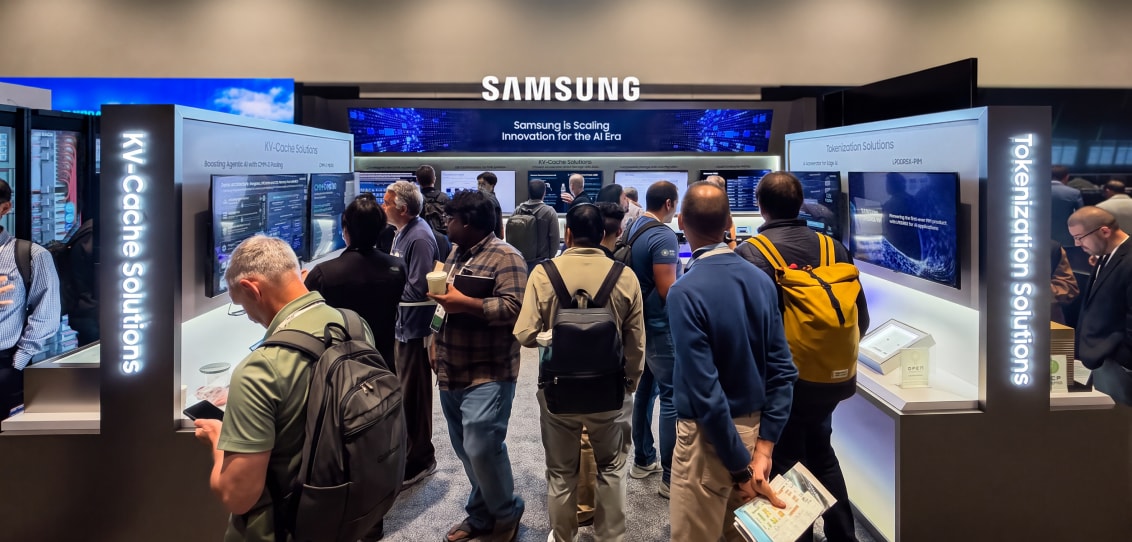
Join Samsung experts in Executive, Expo Hall, and Breakout Sessions to explore how evolving AI workloads are shaping the future
of memory and storage. Gain insights into new architectures, technologies, and approaches for scaling AI infrastructure in the agentic era.
Join Samsung experts in Executive, Expo Hall, and Breakout Sessions to explore how evolving AI workloads are shaping the future of memory and storage. Gain insights into new architectures, technologies, and approaches for scaling AI infrastructure in the agentic era.
Join Samsung experts in Executive, Expo Hall, and Breakout Sessions to explore how evolving AI workloads are shaping the future of memory and storage.
Gain insights into new architectures, technologies, and approaches for scaling AI infrastructure in the agentic era.
Scaling Innovation for the AI Era:
Keep Your Compute Running at Full Throttle with Highly Scalable Memory
Scaling Innovation for the AI Era:
Keep Your Compute Running at Full Throttle with Highly Scalable Memory
Scaling Innovation for the AI Era:
Keep Your Compute Running at Full Throttle with Highly Scalable Memory
Tiering the Agent’s Memory:
From CXL Pooling to SSD-Backed KV Cache Offloading
Tiering the Agent’s Memory:
From CXL Pooling to SSD-Backed KV Cache Offloading
Tiering the Agent’s Memory:
From CXL Pooling to SSD-Backed KV Cache Offloading
Dive deeper into the technologies shaping next-generation AI infrastructure.
Meet our experts and discover how memory and storage innovation is solving today's technical challenges.
Dive deeper into the technologies shaping next-generation AI infrastructure. Meet our experts and discover how memory and storage innovation is solving today's technical challenges.
Dive deeper into the technologies shaping next-generation AI infrastructure. Meet our experts and discover how memory and storage innovation is solving today's technical challenges.
HBM4E
HBM4E
HBM4E
HBM4E
HBM4E
LPDDR5X-PIM
LPDDR5X-PIM
LPDDR5X-PIM
HBM4E
HBM4E
CMM-D MD310
CMM-D MD310
CMM-D MD310
HBM4E
HBM4E
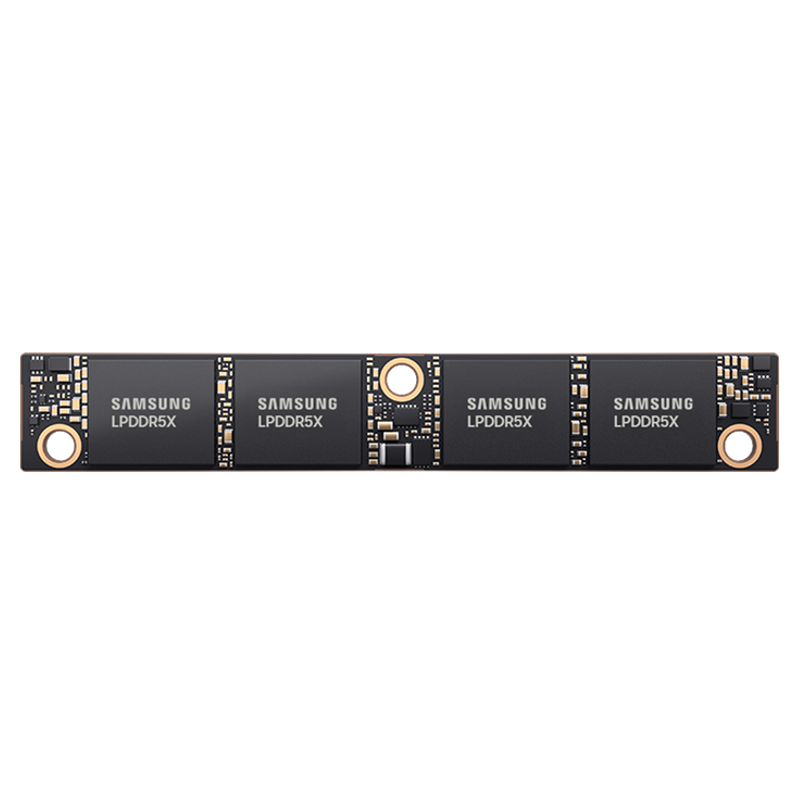
SOCAMM2
SOCAMM2
SOCAMM2
HBM4E
HBM4E
PM1763
PM1763
PM1763
HBM4E
HBM4E
BM1773
BM1773
BM1773
HBM4E
HBM4E
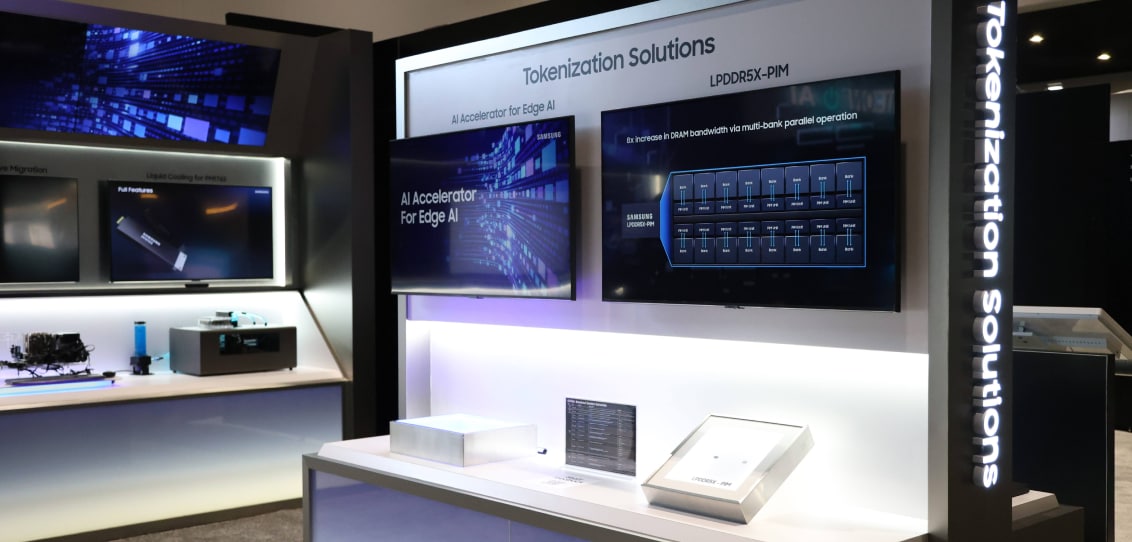
LPDDR5X-PIM delivers up to 8x higher effective bandwidth, boosting LLM performance (TPS) by up to 3x on the Samsung Edge AI Accelerator.
LPDDR5X-PIM provides up to 8x higher effective bandwidth than standard LPDDR5X by integrating PIM Units (PU) into each bank. Performance evaluations of Llama 3.1 8B on the Samsung Edge AI Accelerator system demonstrate that the LPDDR5X-PIM solution improves LLM inference performance (Tokens Per Second, TPS) by up to 3x and reduces execution runtime by up to 2.2x compared to conventional LPDDR5X solutions.
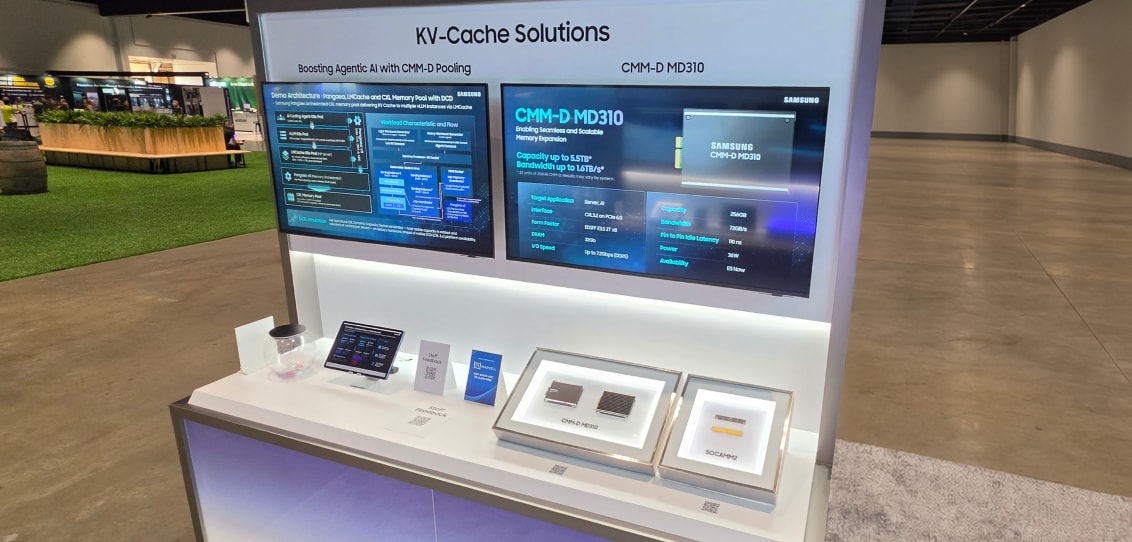
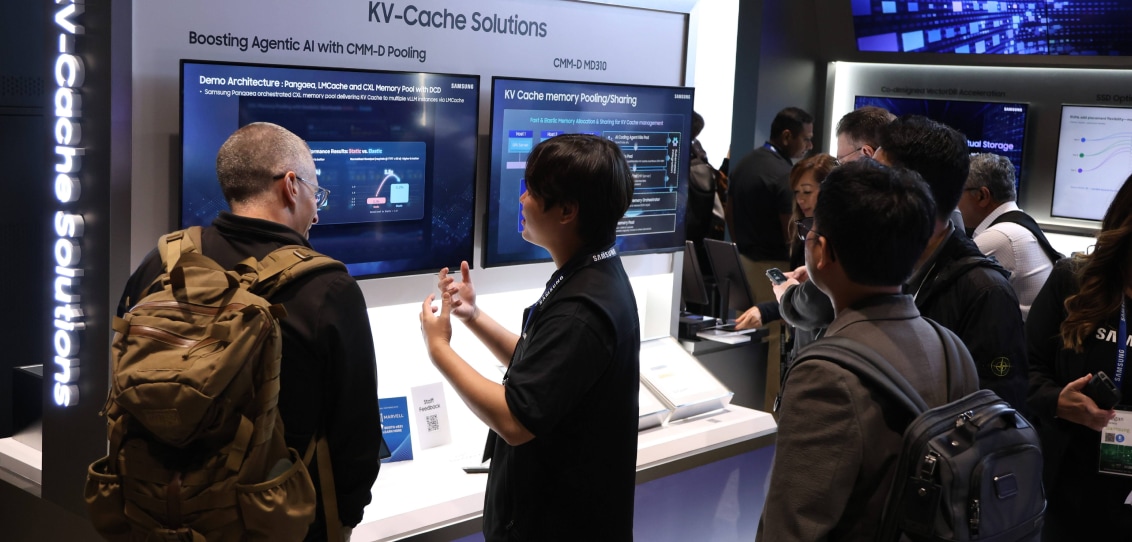
CMM-D provides DCD-based CXL memory pooling with elastic allocation, delivering lower TTFT and higher goodput for LLM inference.
This demo showcases an AI agent workload running on a GPU server, leveraging a DCD-based CXL memory pool with elastic memory allocation to address memory capacity constraints across multiple LLM instances. Elastic memory allocation across instances delivers up to 38% lower TTFT and up to 3.3x higher goodput compared with static allocation.
CMM-D maximizes concurrent agentic AI users by scaling memory capacity and bandwidth with CPU core growth.
Recognizing that agentic AI can drive sharp increases in CPU utilization while memory capacity often fails to keep pace with the growing number of CPU cores, Samsung and AMD collaborated to validate CXL memory as an approach to scaling memory capacity and bandwidth while reducing CPU stalls.
Cognos AI Memory Agent uses CMM-D to scale token throughput and lower cost per user.
This demo showcases a production deployment of the AI Memory Node™ solution with CMM-D at Samsung Semiconductor's US campus, serving an internal AI coding agent and other applications. Adding an L3.5 composable memory tier improved overall tokenomics and delivered 5–7x KV cache utilization. The results come from a collaboration among Samsung's Memory Solutions Lab, the DSA AI Platform Integrations team, and SGLang.
Raise recall without raising PCIe traffic: in-SSD ANN computation scales search throughput with SSD count.
NCVS (NVMe Computational Virtual Storage) is a pathfinding proof of concept that moves vector distance computation into SSDs, returning 4-byte distances instead of 4KB vectors over standard NVMe. Host traffic stays flat across recall targets, up to 22x lower than the host path, while search throughput scales with SSD count. Capacity upgrades become performance upgrades, with no changes to host CPU, DRAM, or interconnect.
Enhancing KV cache efficiency through software-hardware co-optimization using FDP and longer MDTS.
This demo presents KV cache-specific optimizations vertically integrated into LMCache, featuring Flexible Data Placement (FDP) to reduce Write Amplification Factor (WAF) and leveraging a larger NVMe Maximun Data Transfer Size (MDTS) to minimize host CPU cycles. These optimizations provide a scalable path for both node-local and pod-shared KV cache environments, showcasing Samsung's approach to KV cache-native storage solutions.
Eliminating storage I/O bottlenecks through an open-source, vendor-agnostic, highly scalable I/O infrastructure for the new era of accelerator-centric architectures.
AISIO enables GPU-initiated, P2P, and standard CPU-initiated I/O through a common API by integrating Linux Kernel upstream work and popular accelerator frameworks. Leveraging OpenDS, AISIO saturates storage at 100M IOPS and delivers up to 10x improvement in LLM cold-start model loading.
Multi-tenancy and QoS on standard NVMe through industry collaboration on composable SSD architecture
This live demo brings Samsung's industry collaboration on NVMe standardization together in one working implementation: Composable Storage. From data migration to virtual SSD management, the architecture opens a path to multi-tenant storage with enforceable QoS, built on standard NVMe.
A liquid-cooling-optimized SSD delivering high-performance, power-efficient storage for next-generation AI infrastructure.
This demo showcases the PM1763 E1.S SSD integrated into a liquid-cooling system, highlighting its optimized hardware placement for efficient heat dissipation through direct cold-plate contact. As Samsung's next-generation PCIe Gen6 enterprise SSD for AI infrastructure, PM1763 delivers up to 28.4 GB/s sequential read performance and up to 1.8x higher power efficiency than the previous generation.


 Global