Mini-Module
Summary
The Python for Blue Team module is designed for cybersecurity professionals within the Blue Team and Incident responders seeking to enhance Python skills. Throughout this module, students will develop proficiency in Python programming for advanced threat detection and defense, enhanced skills in utilizing Python for cybersecurity analysis and defensive strategies, and advanced understanding of Python's application in a cybersecurity context.
Recommended prior knowledge:
-
Basic understanding of Python programming language
-
Familiarity with cybersecurity concepts and defensive strategies
Web Scraping with Python
What is Web Scraping and Why Should We Know?
Web scraping is the process of parsing the HTML content of a website and extracting data from that content. Web scraping is usually done using automated software or scripts. These scripts typically do the same thing a web browser might do: open a website, find certain information, and collect or store that information in the most effective way.
Web scraping is very useful and widely used in many scenarios. Its use in the security perspective is already our topic, but it would be eye-opening to give examples of other issues where it can be useful:
Data Science and Machine Learning
Most machine learning models need data, and web scraping can be used to collect this data. For example, a person may need to analyze the sentiment of social media comments and use web scraping to collect these comments.
Market Research
Companies and individual researchers can use web scraping to gather information about online product prices, product features, consumer reviews, and more. This can be used to track trends, look at competitor prices, or perform market analysis.
Web Content Scraping
A person or company may use web scraping to gather information about a particular topic. For example, a person can collect all recipes and put them together in a single database.
Data Integration
Web scraping can also be used to collect data from different sites and combine it in one place. This can be used to create a news portal or a price comparison site that provides information from different sources.
Warning: Before continuing with the topic, it is important to remember that Web Scraping applications may cause legal responsibilities. For example, a website's terms of use may prohibit scraping on that site. Additionally, the use of collected data may also be subject to various data protection and privacy laws. Therefore, when starting a web scraping project, it is important to consider these aspects.
Python is an ideal tool for web scraping with its extensive library support and ease of use. In this part of the training, we will cover the basic concepts of web scraping with Python and look at some examples that security professionals can use in their daily work.
Tools for Python Web Scraping
There are many libraries for web scraping in Python such as “Beautiful Soup”, “Scrapy” and “Requests”.
Beautiful Soup
It is a Python library used for web scraping. It is used to parse HTML and XML files.
In fact, “Beautiful Soup” is not a scraper on its own, but a parsing library. Its main power is HTML, XML, etc. It can parse many formats automatically and does not compromise on performance. It needs a library like “requests”, etc. to work.
Although it is a very powerful tool, it is not preferred in very large projects.
Scrapy
It is a more powerful and feature-packed web scraping library than Beautiful Soup. It has various features such as parsing, processing requests, and storing data.
This tool does everything Beautiful Soup does, plus includes its own request libraries. Although it is a bit complicated to learn, it offers highly advanced support in large and complex projects, from optimization of requests to user-agent manipulations, from data storage automation to middleware integrations.
Requests
It is used to send HTTP requests in Python. This library is used to retrieve the content of a web page. There is no parser mechanism in itself. Although it is quite sufficient in cases where the raw response meets your needs, it can be quite tiring as you will be left with string functions to perform complex operations on the returned response.
Python is a wide world to which many developers contribute, and therefore, apart from the ones we have mentioned, there are dozens of different libraries/frameworks, etc. available that are specialized for various purposes. Although we cannot explain all of them here, we recommend that you investigate these options when you have a web scraping project.
Beautiful Soup
Let's start by making a sample of Beautiful Soup together. Let our code be like this:
import requests from bs4
import BeautifulSoup
URL = "https://letsdefend.io"
page = requests.get(URL)
soup = BeautifulSoup(page.content, "html.parser")
results = soup.find("meta", {"name":"description"})

print(results)
When we run it, it is very likely that you will get an output like this:
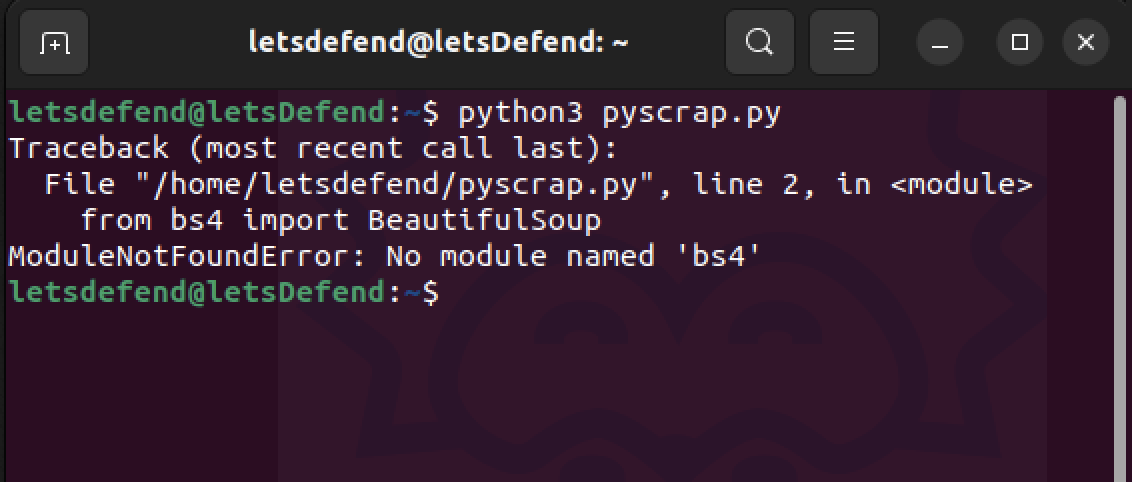
The message here says that the “bs4” library is not yet installed on our system, so we cannot use BeatifulSoup. What we need to do is simple:
pip3 install bs4
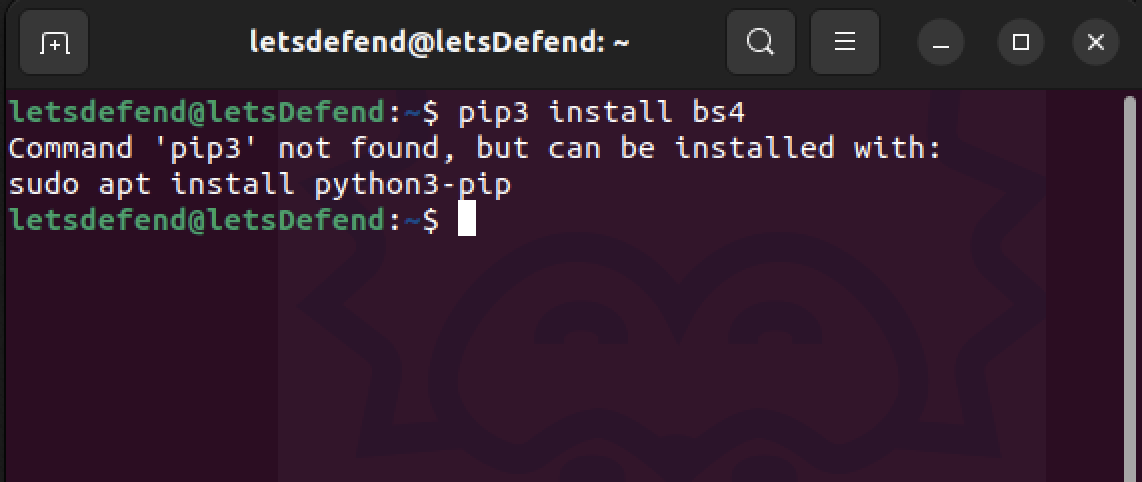
When we wanted to install the bs4 library with pip3 in our Ubuntu 20.4 environment, we received a notification saying that pip3 was not installed yet. Fortunately, there is a notification right below telling us what to do. We immediately ran the sudo apt install python3-pip
command, and then we installed the bs4 library on our system with the pip3 install bs4 command:
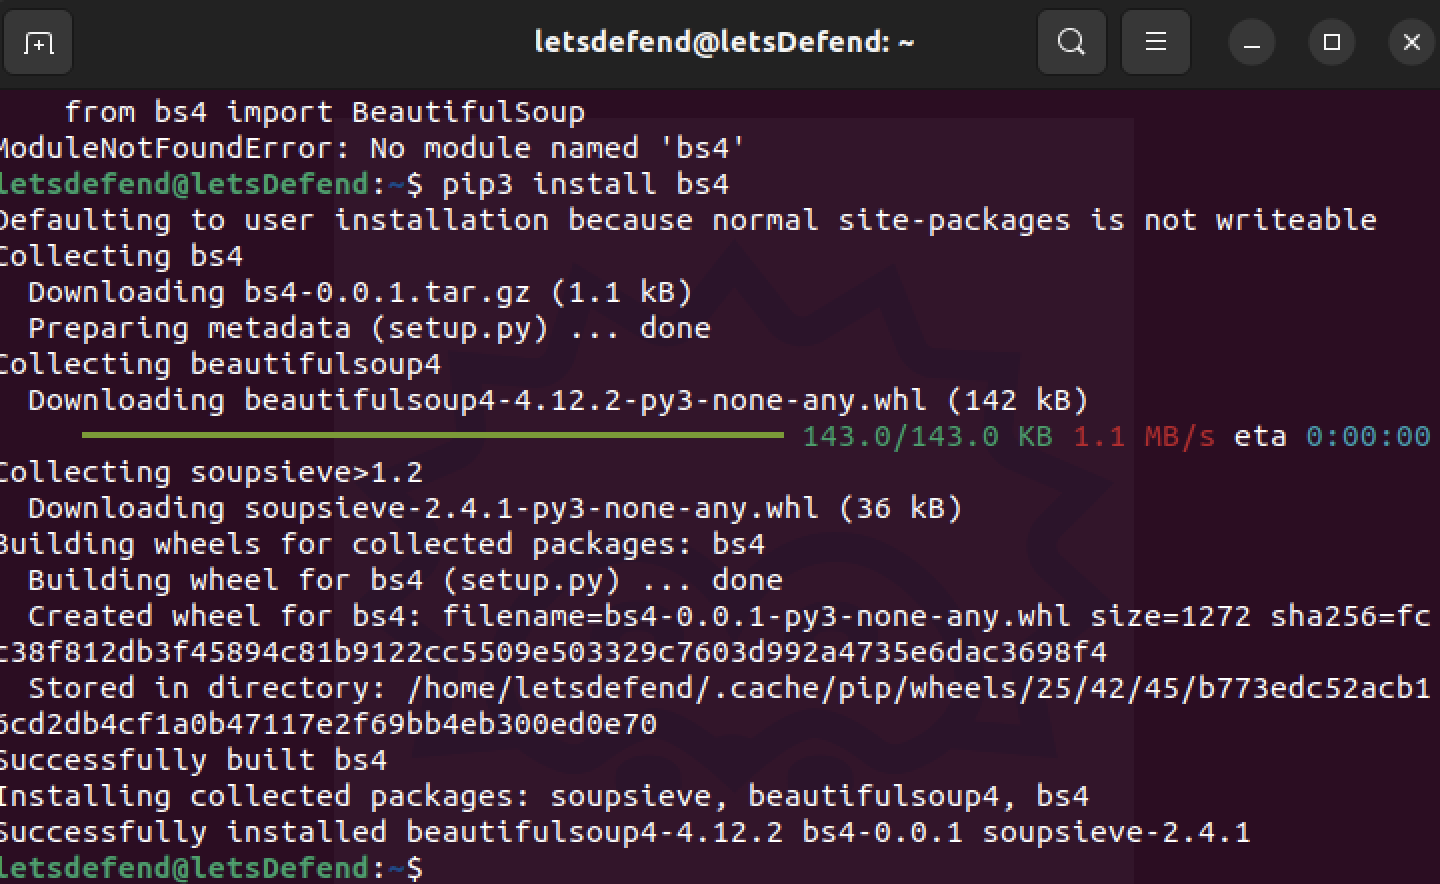
In the later parts of the module, the missing libraries in your system will appear again, in this case, you will need to proceed by installing the missing libraries with pip3, just like we have done here. Now we can get back to work. We think our script will now work:
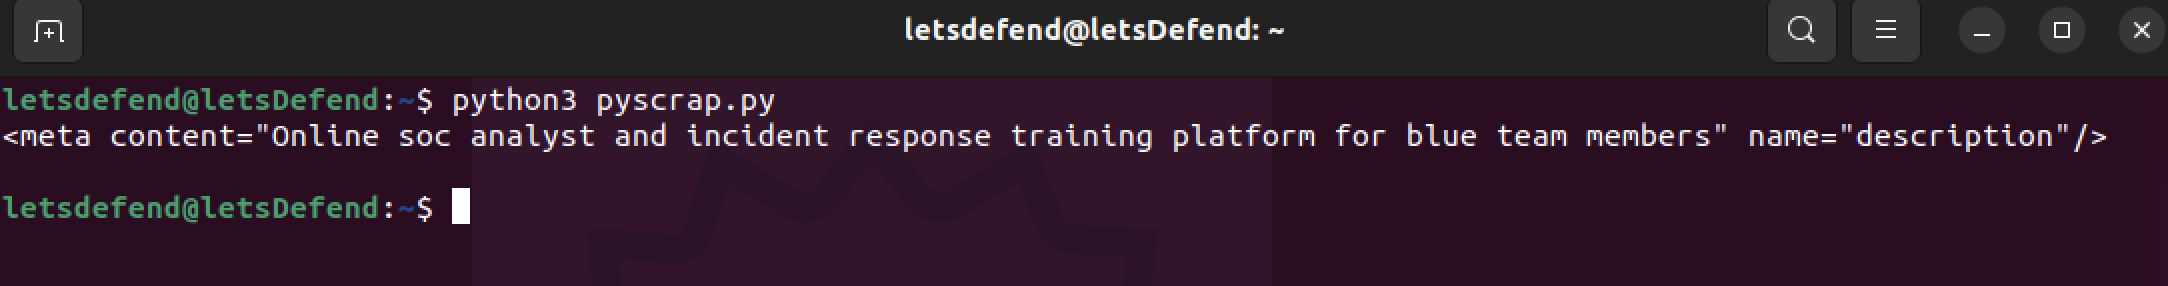
Now let's examine what we did line by line:
import requests from bs4
import BeautifulSoup
In these two lines, the modules required for the operation of the code are included. The "requests" module allows communicating with web servers using the HTTP protocol. "BeautifulSoup" is used to parse HTML and XML documents.
In the next line, we assign the URL of the target website to a variable.
URL = "https://letsdefend.io"
In the next line, an HTTP GET request is sent to the specified URL using the "requests.get()" method. The response to this request is thrown into a variable called "page".
page = requests.get(URL)
In the next line, we create an instance of the BeautifulSoup class. We use BeautifulSoup to parse the content of the retrieved web page. We obtain the content with "page.content" and parse it in HTML format with "html.parser".
soup = BeautifulSoup(page.content, "html.parser")
In the next line, using the "find" method of the BeautifulSoup library, we look for the "meta" tag and the element whose "name" property is "description" in the HTML document. We assign the first match found to the "results" variable.
results = soup.find("meta", {"name":"description"})
And finally, we print the result to the screen:
print(results)
Scrapy
Now let's take a look at how things work with Scrapy:
We first need to create a project with Scrapy. We created our project by naming it “letsdefend_scraper”:
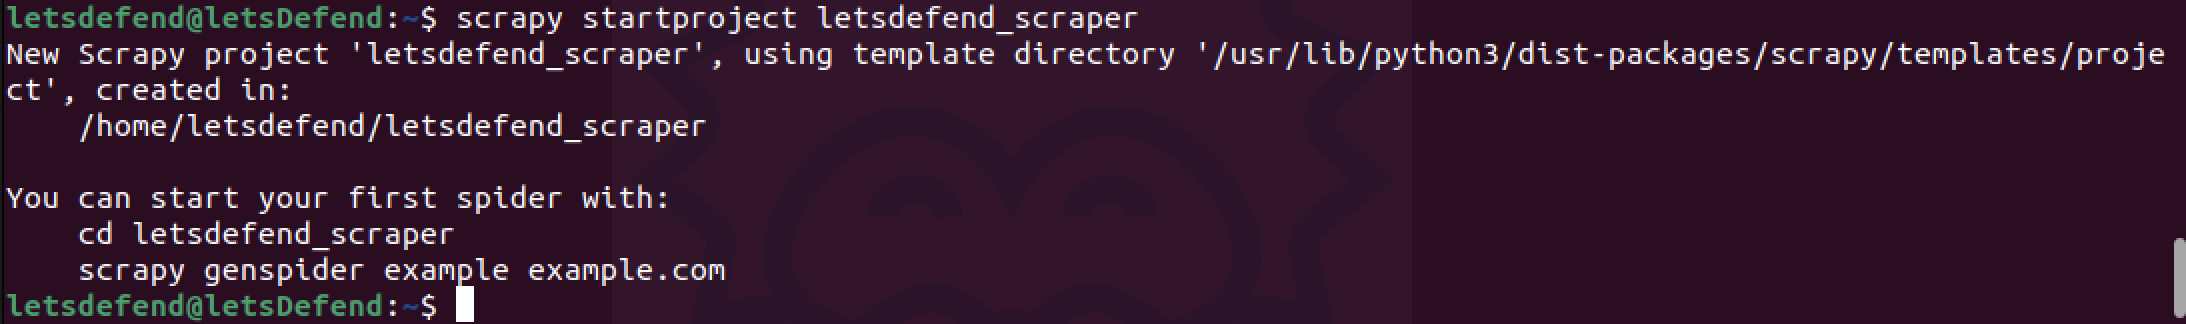
When we ran this command, scrapy created a project directory for us and automatically placed the directories it needed to run in the project directory:
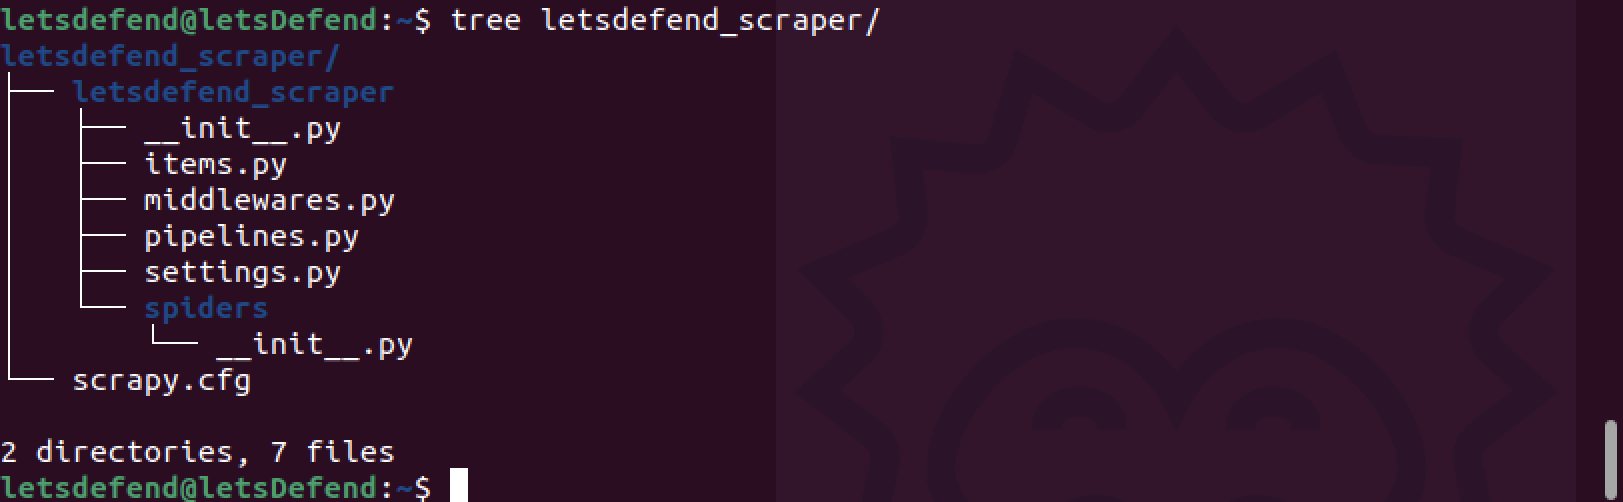
Now all we need to do is to write the code for our purpose and save it in the spiders directory in the project directory.
Let's continue by saving the following code in the spiders directory under the name description_spider.py:
import scrapy

class DescriptionSpider(scrapy.Spider):
    name = 'description'
    start_urls = ['https://letsdefend.io']

    def start_requests(self):
        for url in self.start_urls:
            yield scrapy.Request(url, callback=self.parse_description)

    def parse_description(self, response):
        description = response.xpath('//meta[@name="description"]/@content').get()
        print("Description:", description)
When we run the command, scrapy crawl description
at the letsdefend_scraper directory we will get an output like the following (we have highlighted the part we are looking for with a gray background for you):
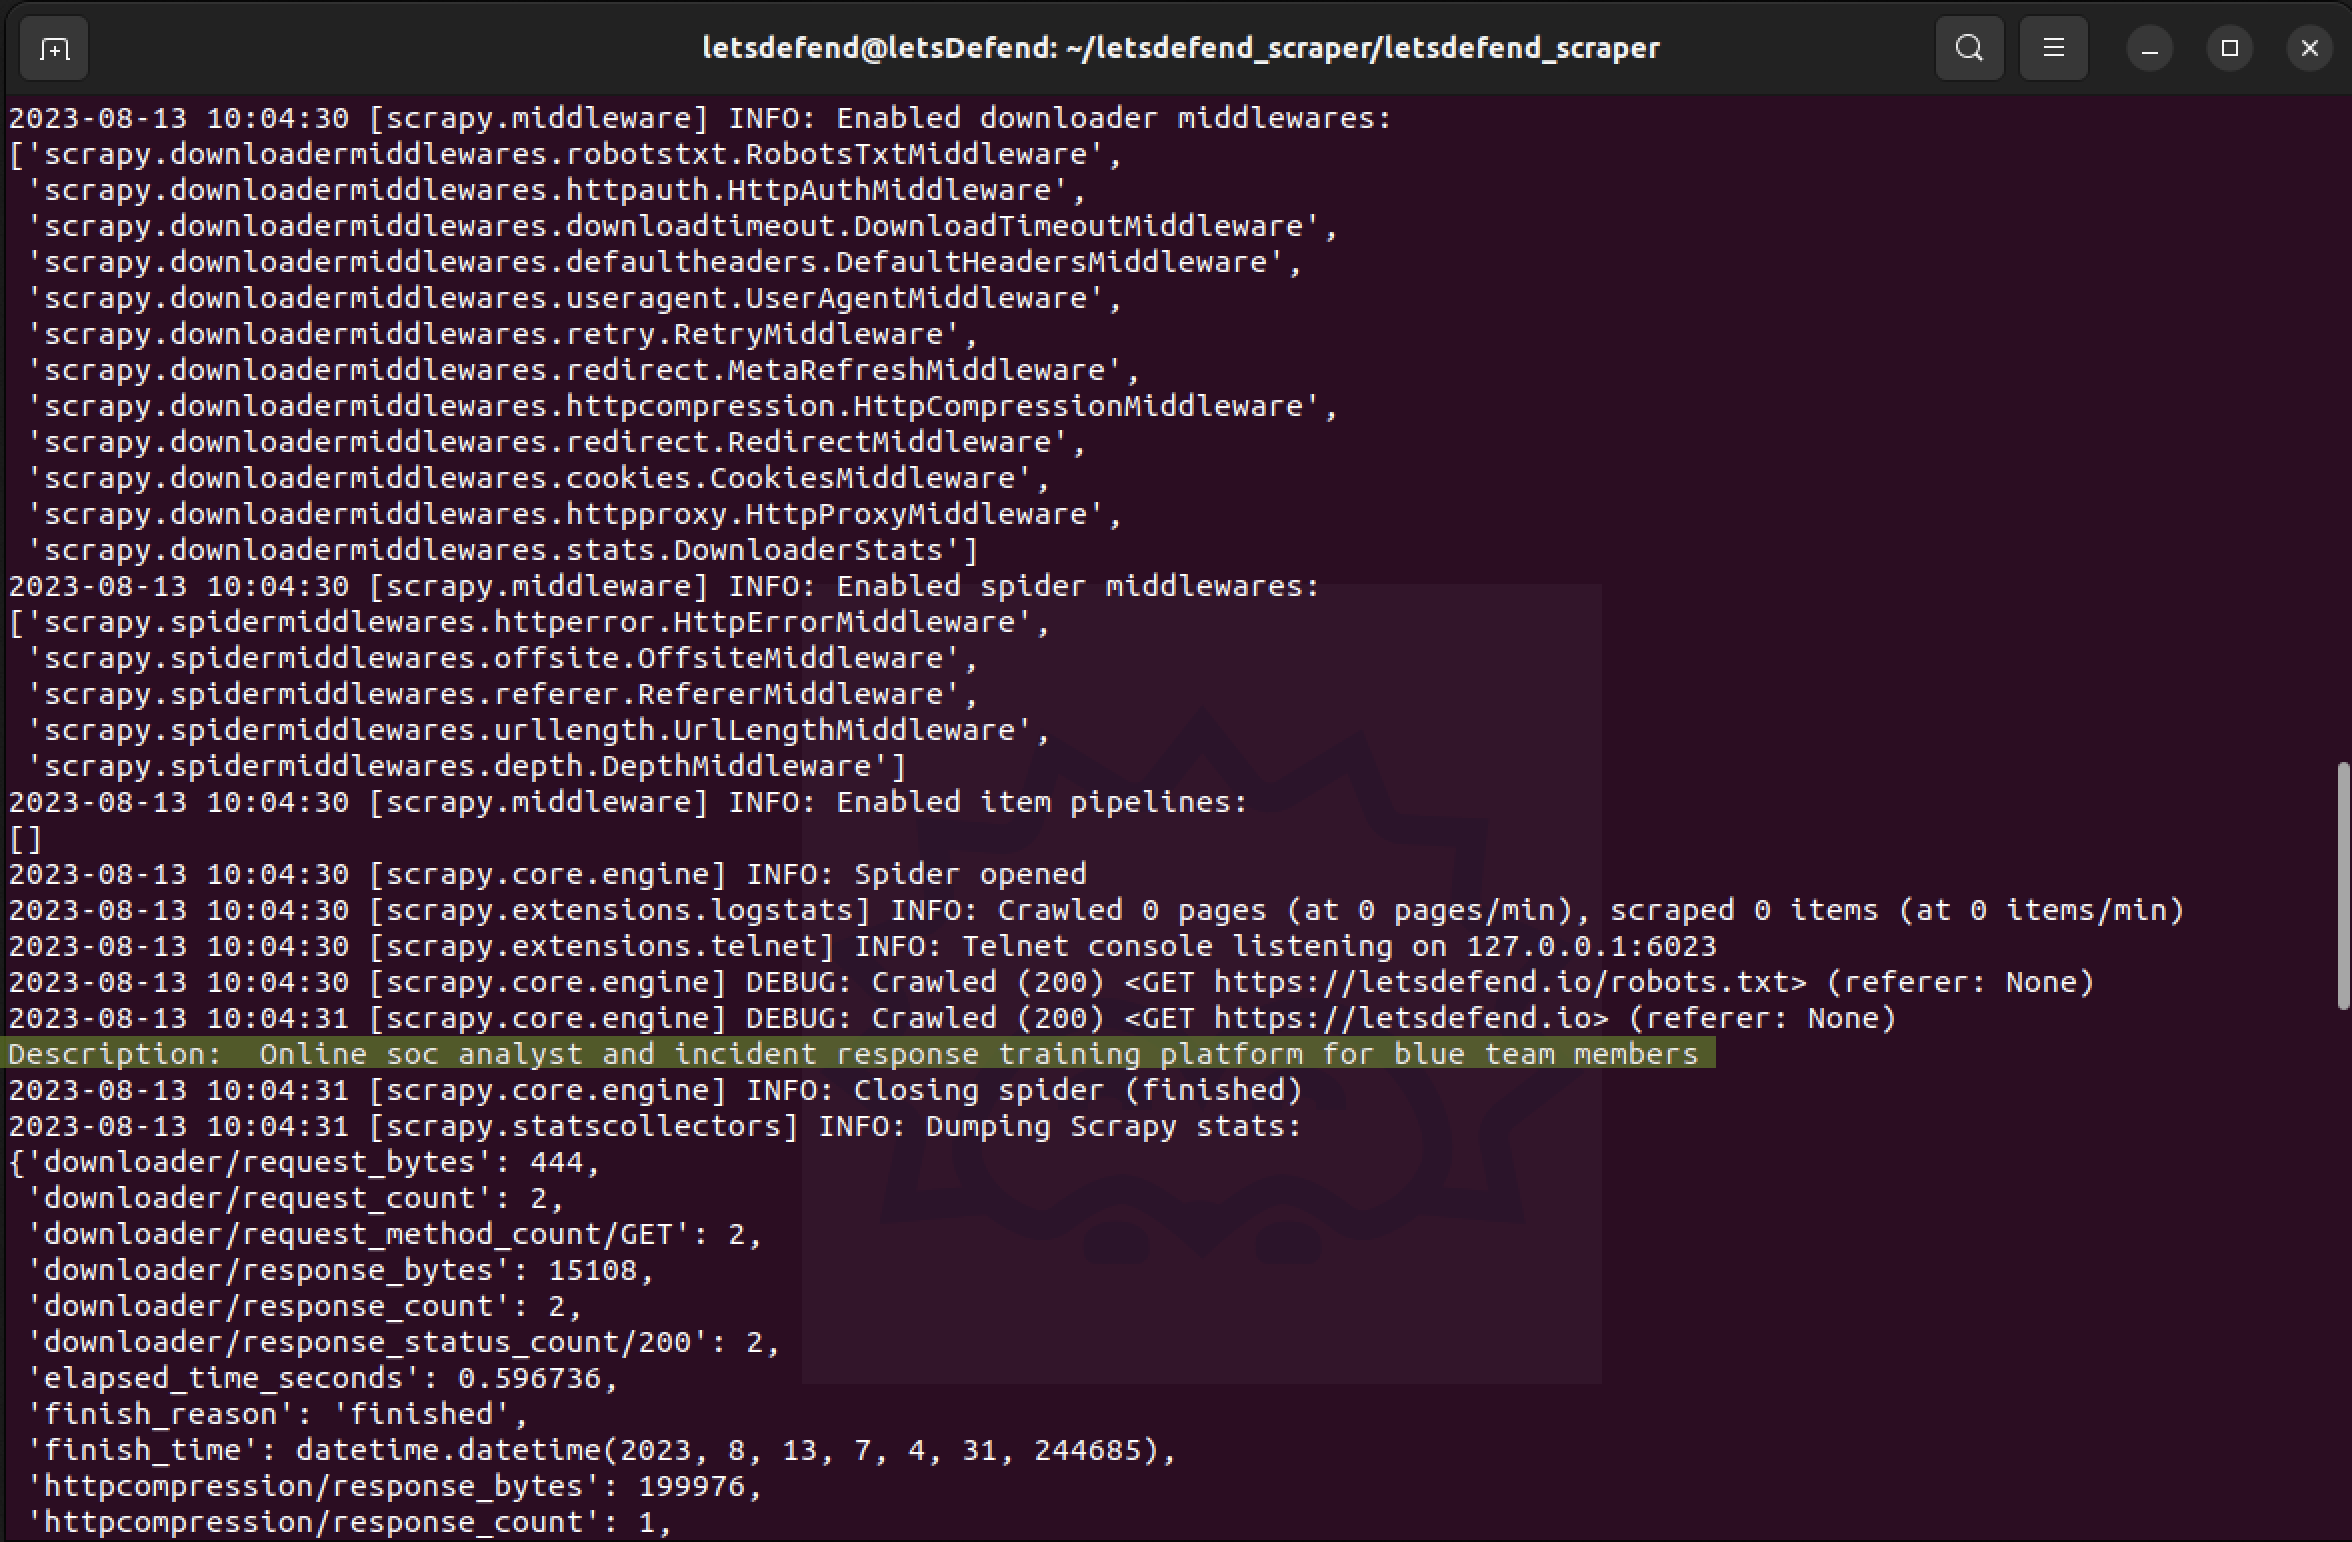
The output looks very complicated, right? Our suggestion to you is to examine and understand the working logic of Scrapy on each line in this output. Then, all you have to do is to add the
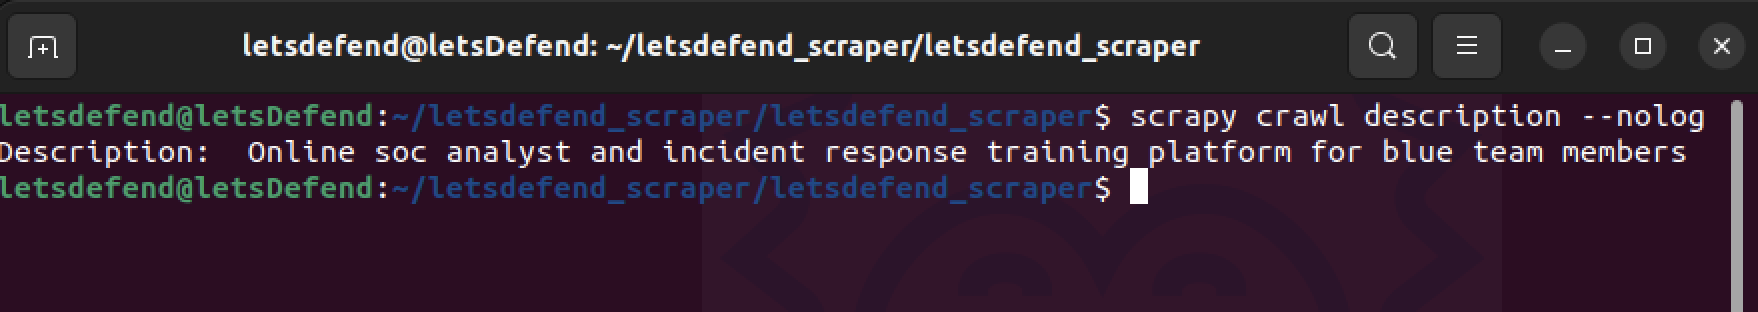
–nolog parameter
to the end of your command to see the cleaner output you requested:
Requests
We already used requests above, with page = requests.get(URL) in Line 4 of our BeatifulSoup example. Then we processed the response by giving it to BeatifulSoup's HTML parser. We don't actually need this for simple tasks that don't require Performance and Optimization. We can parse the data we are looking for by using Python's built-in string functions within the content we receive with Python requests.
Let's look at an example:
import scrapy
class DescriptionSpider(scrapy.Spider):
    name = 'description'
    start_urls = ['https://letsdefend.io']

def start_requests(self):
    for url in self.start_urls:
    yield scrapy.Request(url, callback=self.parse_description)

def parse_description(self, response):
    description = response.xpath('//meta[@name="description"]/@content').get()
    print("Description: ", description)
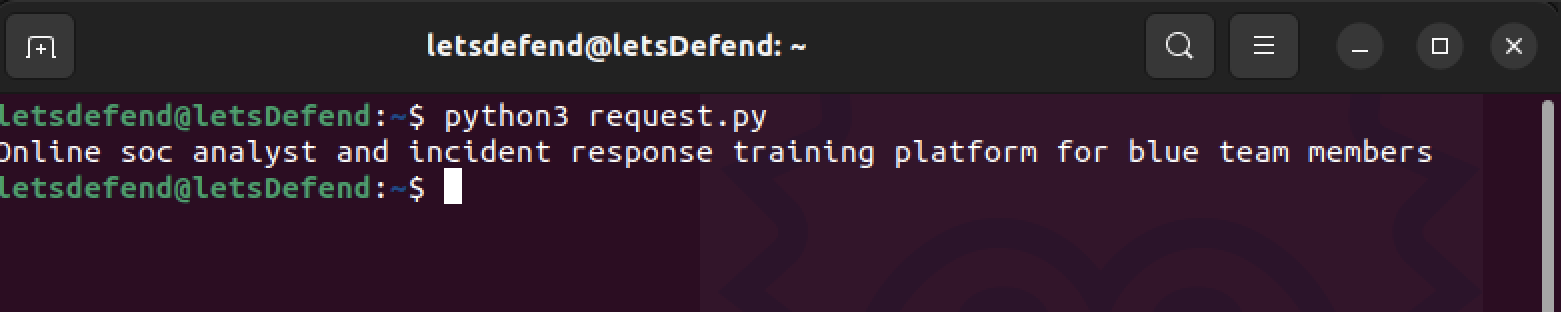
When we save and run the above code as “request.py”, we get the following output:
In this part of the training, we have covered what web scraping is, important items to know about web scraping and some tools and usage examples that can be used for web scraping in Python. In the next part of the training, we will be learning about the Web Scraping Lab with Python topic.